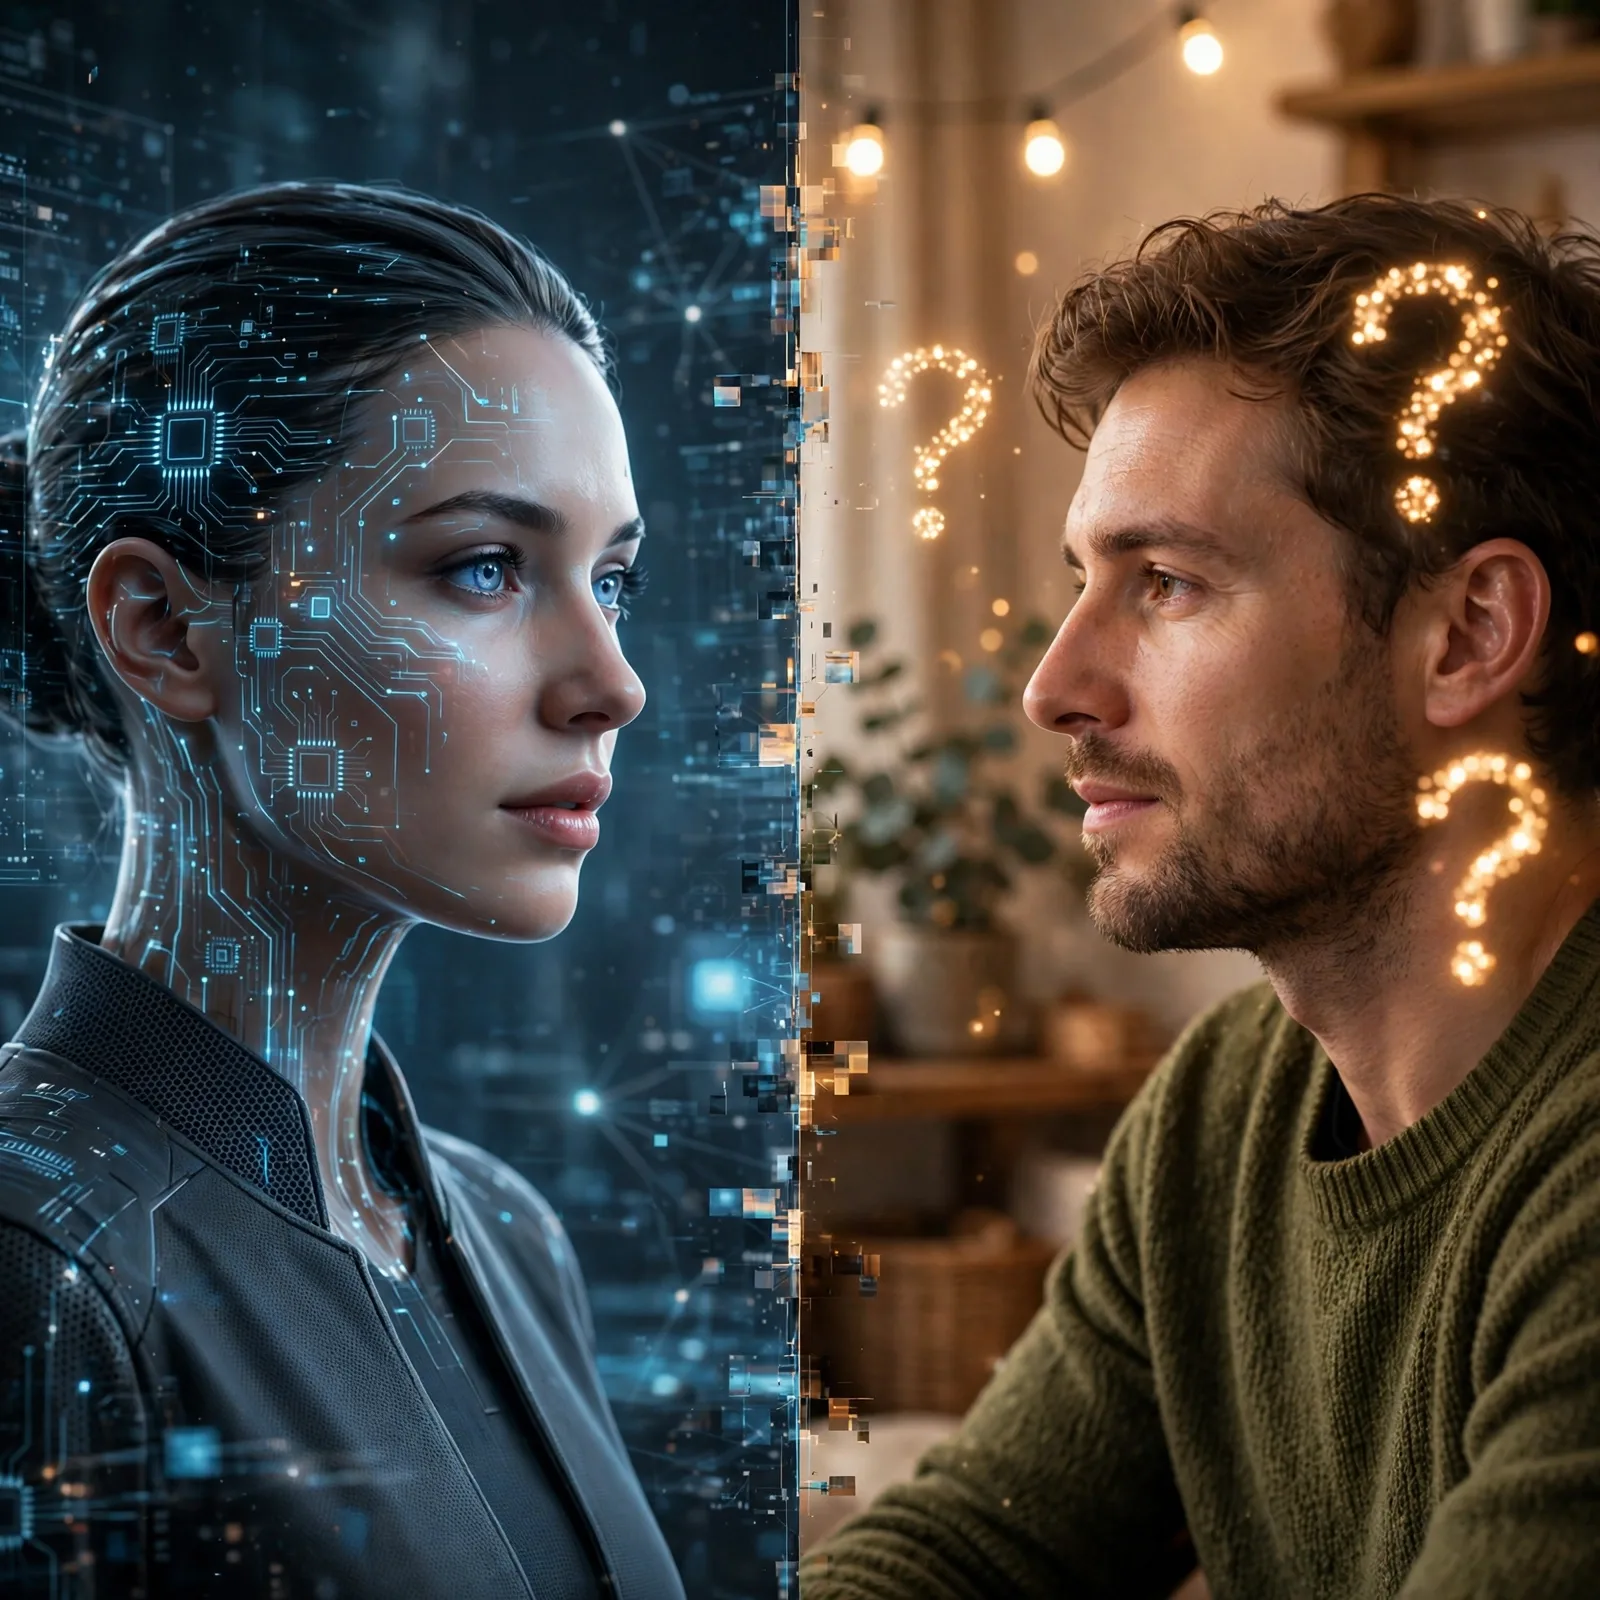
What Tavus announced
On October 1, 2026, Tavus introduced Griffin, which it calls the first Human Interaction Model (HIM) — "a new class of models designed to understand and generate face-to-face real-time human interaction. They listen while they talk, and they pay attention to expressions and pauses, not just words." Griffin-Lite, a research preview, is available to a select group of early testers; Tavus says a wider release of a more powerful Griffin model will follow after safety work, including AI identity disclosure features.
The 48% study — and its limits
Tavus's headline: in a live study, 48% of participants who talked with Griffin for one minute thought they had spoken with a real human. The numbers: 26 of 54 participants judged the Griffin-Lite call partner to be human, versus 1 of 41 (2.4%) for Tavus's previous system — a Phoenix-4.5, Sparrow-2, and Raven-1 pipeline. Participants were told they would have a one-minute video call with another participant; only afterward were they asked whether it had crossed their mind the partner might not be real.
How Griffin works: the two-part system
- Continuous Conversational Modeling engine — perceives incoming audio and video, decides when and how to respond, emits control signals for speech, emotion, expression, and gesture
- Audio-Visual Generation engine — streaming speech generation plus streaming video generation that convert those signals into voice and 720p video in real time
- Sub-second mini-turns — the model reassesses the conversation many times per second, so it can nod, backchannel ("mm-hm"), interrupt, or yield while you are still talking
- Full-scene generation — every pixel of every frame is generated from one reference image, including background, chair, and shadows
- Perception never stops — the model keeps watching and listening even while it speaks
What full-duplex changes versus old video avatars
Legacy video agents chain separate systems — speech recognition, language model, speech synthesis, avatar rendering — so they wait for you to finish, then think, then talk. Griffin folds perception, decision-making, and generation into one concurrent loop: a pause for thought is not mistaken for the end of a turn, an interruption stops the model mid-sentence without losing context, and visual cues (a confused face, something held up to the camera) shape the response in real time. Tavus reports average audio-to-video latency of 0.43 seconds on Nvidia H100 GPUs.
Benchmarks and capabilities
Tavus says Griffin ranked #1 on Nvidia's VideoFDB evaluation for real-time full-duplex AI video, with reported generation and perception scores of 3.83 and 3.73 out of 5, and claims a 37% advantage in real-time reactivity over the next AI system. Demonstrated capabilities include behavior and emotion modeling (laughing, tone shifts), temporal understanding (tracking how long a silence has lasted and when to speak again), and reacting to on-camera objects — in one demo, Griffin coaches a user through a Rubik's Cube solve while watching the cube turn.
“Talking to a machine should feel as natural as chatting with a friend or colleague.”
Safety and what comes next
Tavus is explicit that realism is also a risk: the company is withholding customer access until it ships AI identity disclosure features, because a system this convincing could deceive people into believing they are not talking to AI. Griffin-Lite stays with trusted testers while safety and alignment work continues; the wider Griffin release comes after.
Frequently Asked Questions
What is Tavus Griffin?
Griffin is Tavus's Human Interaction Model (HIM), introduced October 1, 2026: a full-duplex video-to-video system that perceives incoming audio and video, decides when and how to respond at sub-second intervals, and generates expressive speech plus 720p video in one real-time loop. Griffin-Lite is the research preview available to select testers.
Did Griffin really pass the video Turing test?
In Tavus's own study, 26 of 54 participants (48%) believed their one-minute call partner was human, versus 1 of 41 (2.4%) for the previous system. But participants were not warned an AI might be on the call, and the test was company-run, not independently replicated — so it is a striking result, not a certified Turing-test pass.
How is Griffin different from previous AI avatars?
Old systems chain separate models for speech recognition, language, speech synthesis, and face animation, forcing awkward turn-taking. Griffin runs perception, conversational decision-making, and generation concurrently, so it can interrupt, backchannel, react to visual cues, and adjust expressions mid-conversation — and it generates the whole scene, not just the face.
Can I use Griffin today?
Not yet. Griffin-Lite is limited to a select group of research testers. Tavus says it is withholding customer access until it completes safety work, including AI identity disclosure features; a wider release of a more powerful Griffin model is planned afterward. No price has been published.
What should creators and businesses watch for?
Two things: the capability — full-duplex timing and whole-scene generation set a new bar for conversational video — and the trust question. Clear AI disclosure, consent, and error handling will decide whether this technology deploys responsibly in support, training, and sales roles.
Related Prompts
Conceptual Packaging Design Prompt — One Truth, One Clever Pack Idea
ChatGPT
Vintage Lithograph Poster Prompt — Two-Ink Print, Bold Posterized Art
ChatGPT
Event Poster Design Template Prompt — Any Theme, One Striking Layout
ChatGPT